Let's learn about Web Scraping via these 224 free blog posts. They are ordered by HackerNoon reader engagement data. Visit the Learn Repo or LearnRepo.com to find the most read blog posts about any technology.
Data is the new oil, sun, and the moon! This tag is sponsored by Bright Data. Write a story on web scraping for AI and win from $2500!
1. JSON Lines format: Why jsonl is better than a regular JSON for web scraping
 <strong>Comma Separated Values (CSV) format</strong> is a common data exchange format used widely for representing sets of records with identical list of fields.
2. How To Scrape Google With Python
 Ever since Google Web Search API deprecation in 2011, I've been searching for an alternative. I need a way to get links from Google search into my Python script. So I made my own, and here is a quick guide on scraping Google searches with requests and Beautiful Soup.
3. How to Scrape Yahoo Finance Data with Python
 Financial market data is one of the most valuable data in the current time. If analyzed correctly, it holds the potential of turning an organisation’s economic issues upside down. Among a few of them, Yahoo finance is one such website which provides free access to this valuable data of stocks and commodities prices. In this blog, we are going to implement a simple web crawler in python which will help us in scraping yahoo finance website. Some of the applications of scraping Yahoo finance data can be forecasting stock prices, predicting market sentiment towards a stock, gaining an investive edge and cryptocurrency trading. Also, the process of generating investment plans can make good use of this data!
4. How to Scrape Data from Google Maps Using Python
 Learn how to easily extract valuable information from Google Maps using Python with our step-by-step guide.
5. Intro to Digital Fingerprints: Understanding, Manipulating, and Defending Against Online Tracking
 Digital fingerprinting, identifying users by hardware params. Learn about parameters, manipulation, fingerprint spoofing, online privacy, bot detection systems
6. Python for Data Science: How to Scrape Website Data via the Internet's Top 300 APIs

7. How to Scrape Data From Any Website With JavaScript
 Learn how to scrape the web using scripts written in node.js to automate scraping data off of the website and using it for whatever purpose.
8. How I Successfully "Reverse-Engineered" ChatGPT to Create an Unofficial API Wrapper
 Scraping ChatGPT with Python
9. Scraping Information From LinkedIn Into CSV using Python
 In this post, we are going to scrape data from Linkedin using Python and a Web Scraping Tool. We are going to extract Company Name, Website, Industry, Company Size, Number of employees, Headquarters Address, and Specialties.
10. Scraping Tweet Replies with Python and Tweepy Twitter API [A Step-by-Step Guide]
 A Quick Method To Extract Tweets and Replies For Free
11. How To Scrap Product Information With Python & BeautifulSoup Module From Amazon Listings [Tutorial]
 Intro
12. A Guide to Web Scraping With JavaScript and Node.js
 With the massive increase in the volume of data on the Internet, this technique is becoming increasingly beneficial in retrieving information from websites and applying them for various use cases. Typically, web data extraction involves making a request to the given web page, accessing its HTML code, and parsing that code to harvest some information. Since JavaScript is excellent at manipulating the DOM (Document Object Model) inside a web browser, creating data extraction scripts in Node.js can be extremely versatile. Hence, this tutorial focuses on javascript web scraping.
13. Web Scraping Sites With Session Cookie Authentication Using NodeJS Request
 Web scraping as a product has low entry requirements, which attracts freelancers and development teams to it.
14. Scraping Google Search Results With Node JS
 In this post, we will learn web scraping Google with Node JS using some of the in-demand web scraping and web parsing libraries present in Node JS.
15. Writing a Web Scraper With ChatGPT. How Good is It?
 Is AI capable of writing web scrapers or at least help write some? Is it capable of finding the right selectors by itself? We find out..
16. How To Create A Slick iOS Widget In JavaScript
 With a Scriptable app, it’s possible to create a native iOS widget even with basic JavaScript knowledge.
17. How POST Requests with Python Make Web Scraping Easier
 To scrape a website, it’s common to send GET requests, but it's useful to know how to send data. In this article, we'll see how to start with POST requests.
18. Running a Python Script to Scrape LinkedIn Profiles From Google
 LinkedIn is a great place to find leads and engage with prospects. In order to engage with potential leads, you’ll need a list of users to contact. However, getting that list might be difficult because LinkedIn has made it difficult for web scraping tools. That is why I made a script to search Google for potential LinkedIn user and company profiles.
19. Cracking the Code of Cloudflare Bypass
 Your web scraper has just been blocked by Cloudflare again! Here's solution to bypassing Cloudflare.
20. I Built a Python Script to Make 10,000 Laws Understandable
 Built an AI tool that scrapes, cleans, and summarizes Texas bills to make government legislation readable and transparent for everyone.
21. Why Everyone is Panic-Buying Mac Minis for OpenClaw / Moltbot / Clawdbot?
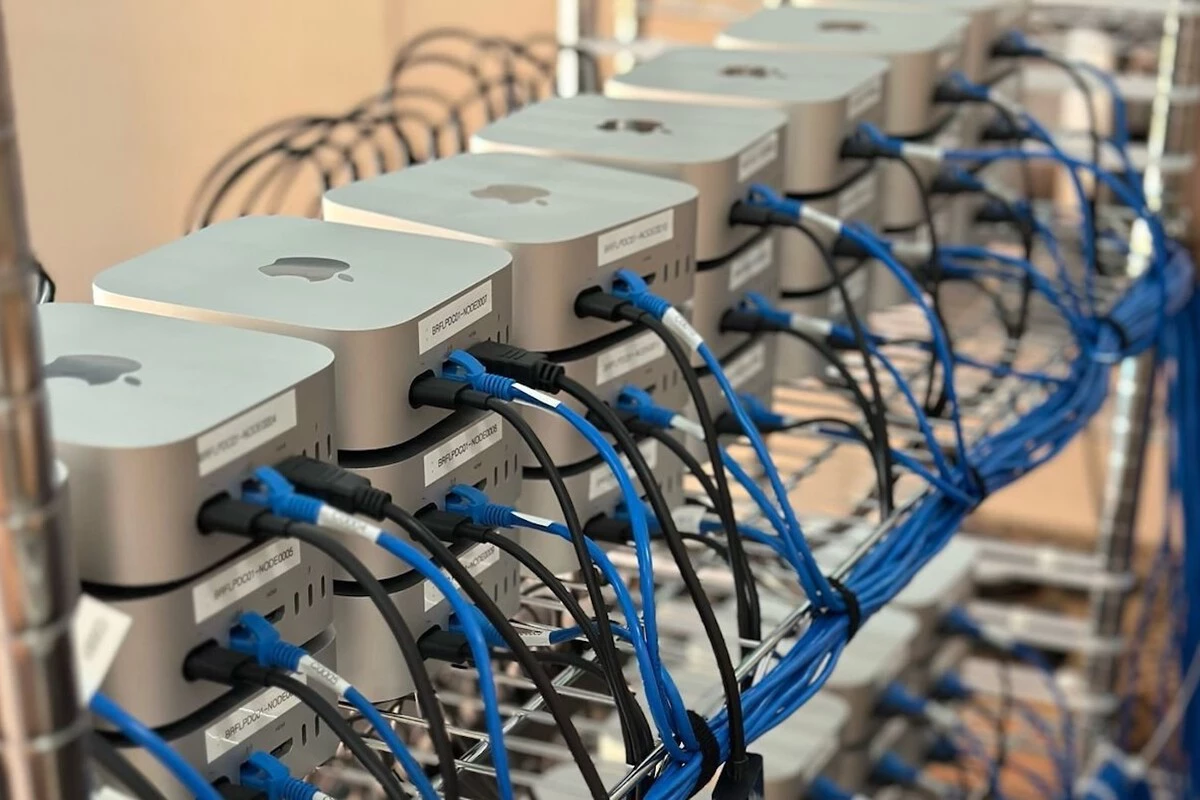 the reality is more nuanced than the hype suggests.
22. How AI Automates Data Scraping and Data Analysis
 There are numerous ways that AI can help us in data scraping and data analysis. Check out these tools and methods!
23. An Intro to No-Code Web Scraping
 Web scraping has broken the barriers of programming and can now be done in a much simpler and easier manner without using a single line of code.
24. How to Scrape a Medium Publication: A Python Tutorial for Beginners
 A while ago I was trying to perform an analysis of a Medium publication for a personal project. But getting the data was a problem – scraping only the publication’s home page does not guarantee that you get all the data you want.
25. 8 Browser Extensions for Scraping Google Maps like a Pro
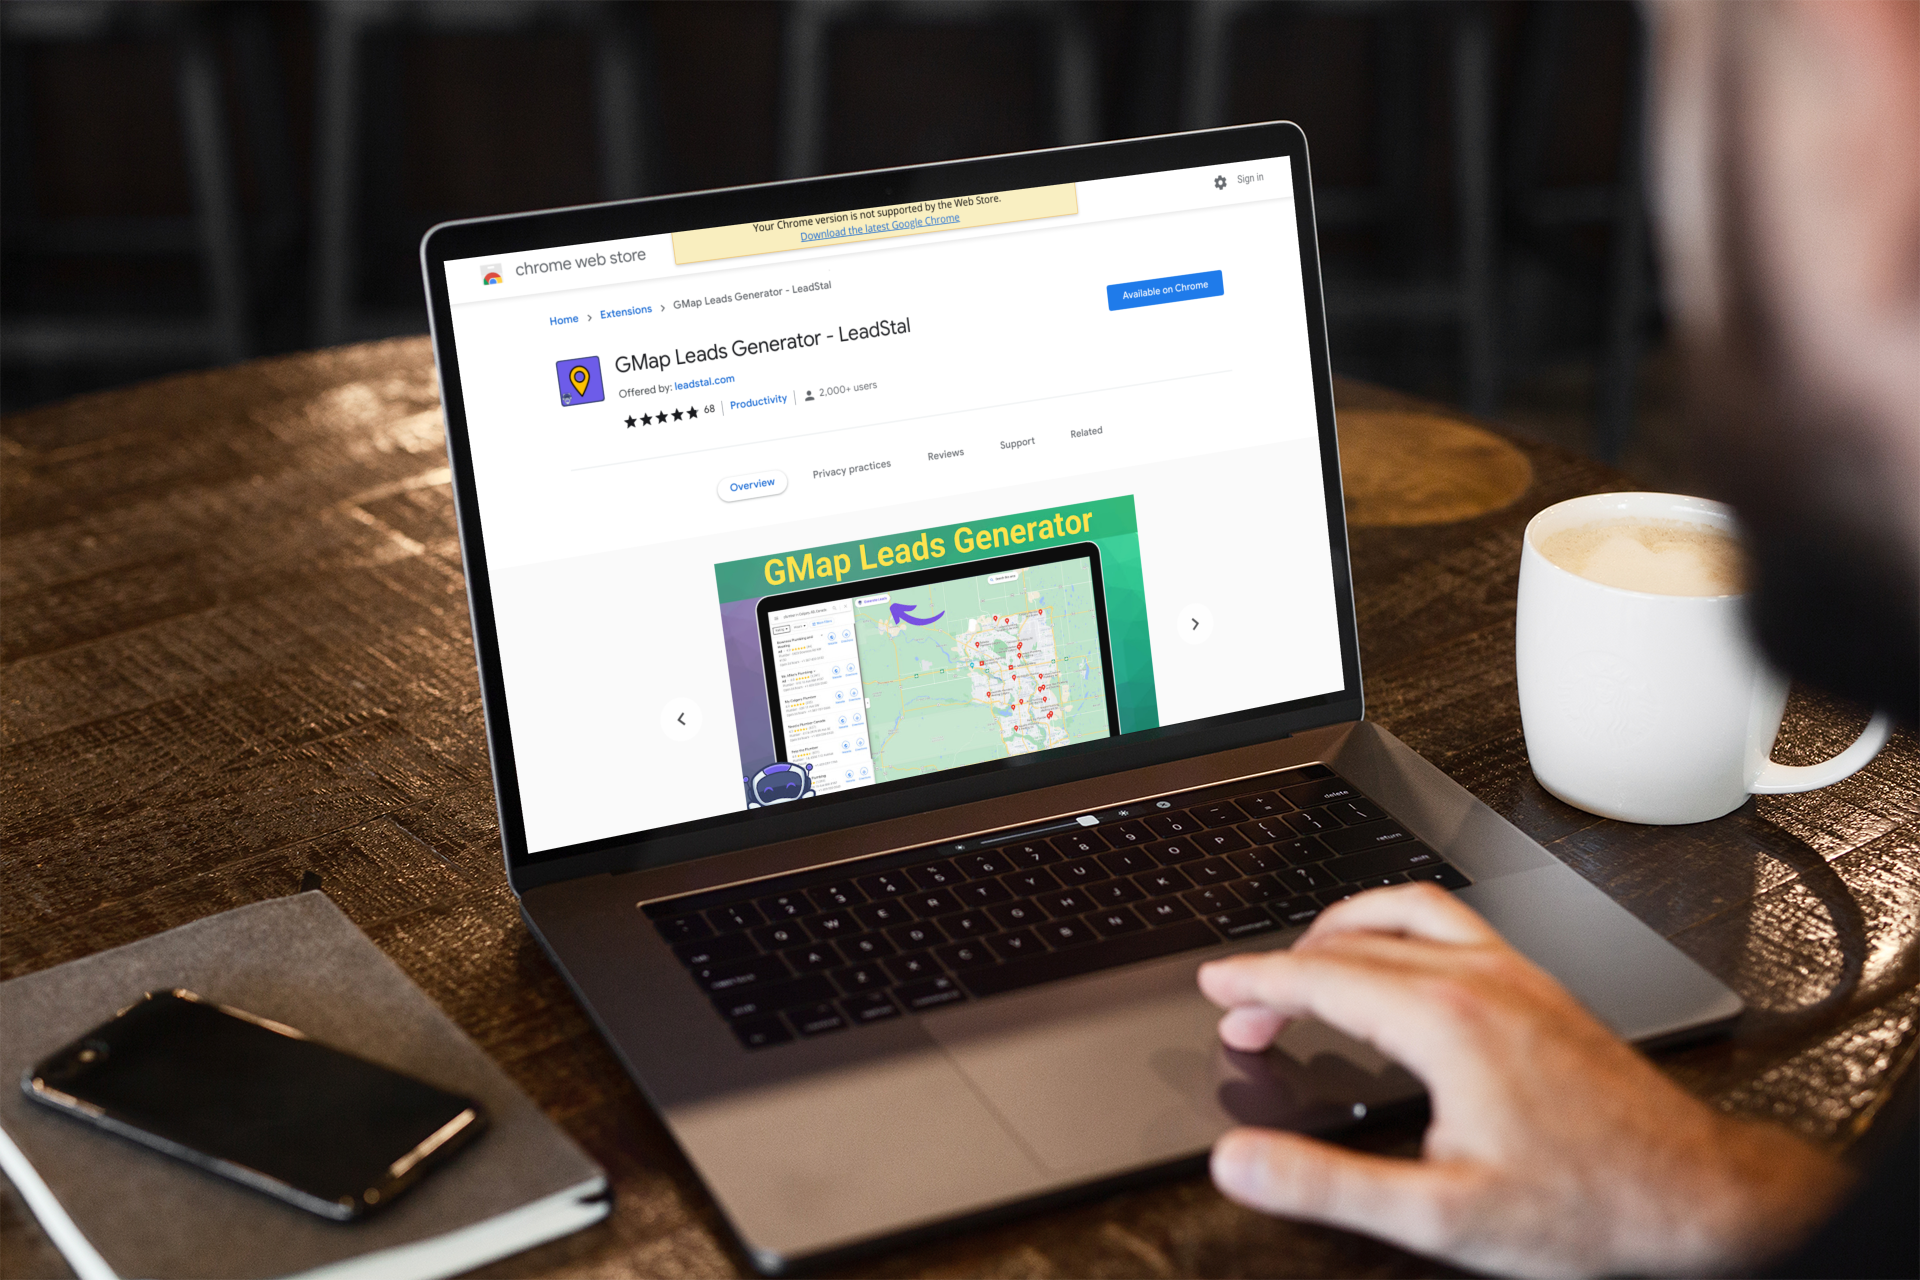 These extensions for scraping Google maps can be used for a number of purposes in various situations that can be either data collection or market research.
26. How to Build a Python Web Scraper: Scrape Data from any Website
 Web scraping is all about programmatically using Python or any other programming language to download, clean, and use the data from a web page.
27. Web Scraping con Python: Guía Paso a Paso
 La necesidad de extraer datos de sitios web está aumentando. Cuando realizamos proyectos relacionados con datos, como el monitoreo de precios, análisis de negocios o agregador de noticias, siempre tendremos que registrar los datos de los sitios web. Sin embargo, copiar y pegar datos línea por línea ha quedado desactualizado. En este artículo, le enseñaremos cómo convertirse en un "experto" en la extracción de datos de sitios web, que consiste en hacer web scraping con python.
28. An Introduction to Email Scraping
 Let's find out what email scraping is, how you can use it, and what's more important: whether it's legal or not.
29. Surviving the Google SERP Data Crisis
 Let's explore why SEO SERP data is now facing outages due to Google's new restrictions on web scraping.
30. Web Scraping and the Battle for Open Internet
 A few years ago, Cambridge Analytica made netizens concerned regarding the gathering of their online data. At that time, affected or interested users had little knowledge of how big the big-data industry actually was.
31. How Do I Build a LinkedIn Scraper For Free?
 Check out this step-by-step guide on how to build your own LinkedIn scraper for free!
32. PHP Web Scraping Using Goutte
 When you talk about web scraping, PHP is the last thing most people think about.
33. Web Scraping con Python: Guía Paso a Paso
 La necesidad de extraer datos de sitios web está aumentando. Cuando realizamos proyectos relacionados con datos, como el monitoreo de precios, análisis de negocios o agregador de noticias, siempre tendremos que registrar los datos de los sitios web. Sin embargo, copiar y pegar datos línea por línea ha quedado desactualizado. En este artículo, le enseñaremos cómo convertirse en un "experto" en la extracción de datos de sitios web, que consiste en hacer web scraping con python.
34. Scraping Amazon using Puppeteer and Browserless
 An easy tutorial showcasing the power of puppeteer and browserless. Scrape Amazon.com to gather prices of specific items automatically!
35. How to Scrape Data from Google Maps
 Want to scrape data from Google Maps? This tutorial shows you how to do it.
36. How To Create a Google SERP Checker in Python
 The goal of SEO is to get your website to the top of the search engine. One excellent way of tracking SEO progress is by checking the Search engine result pages (SERPs) of a website.
37. Build A Web Crawler with Search bar Using Wget and Manticore [A Step By Step Guide]
 Hi everyone. In this article we are going to talk about how can you write a simple web scraper and a little search application using well known existing technologies which you perhaps didn’t know they can do that.
38. AI and Proxies: Are They Connected?
 Explore how proxies power AI—from web scraping to automation—helping bots gather data, avoid bans, and operate smarter, faster, and globally.
39. The Web Scraping Anti-Detect Anti-Bot Matrix: A Guide
 Web scraping tools and framework comparison to bypass the most common anti-bot solutions like Cloudflare, Perimeterx, Datadome, Kasada and F5
40. Python Script to Read and Judge 1,500 Legal Cases
 What started as a simple script evolved into a full-fledged data engineering and NLP pipeline that can process a decade's worth of legal decisions in minutes.
41. How to Scrape Kasada Protected Websites
 How to scrape Kasada-protected websites with Python and other tools, both free and commercial
42. Vote Bot: Create a Voting Bot Without Coding
 Learn how to create a voting bot without coding using Automatio.ai. This guide helps you automate votes for online polls and contests.
43. How to Start with Web Scraping and Why You Don't Need to Code
 Collecting data from the web can be the core of data science. In this article, we'll see how to start with scraping with or without having to write code.
44. Writing a Scraping Bot with Python and Selenium
 Learning how to use Selenium and Python to interact with websites to get the data you need.
45. A Guide to Scraping HTML Tables with Pandas and BeautifulSoup
 How to not get stuck when collecting tabular data from the internet.
46. How to Use .NET C# for Web Scraping
 A guide on how to do Web Scraping in DotNet (.NET) CSharp (C#), with examples. Software Development Coding Programming Selenium HtmlAgilityPack Puppeteer
47. Why AI Agents Must Discover New Sources, Not Just Rely on Cached Search
 Cached retrieval misses new and long-tail sources. Agents need link discovery on the live web to stay accurate and up to date. Learn the model.
48. How to Scrape (Almost) Anything With Puppeteer and Node.js
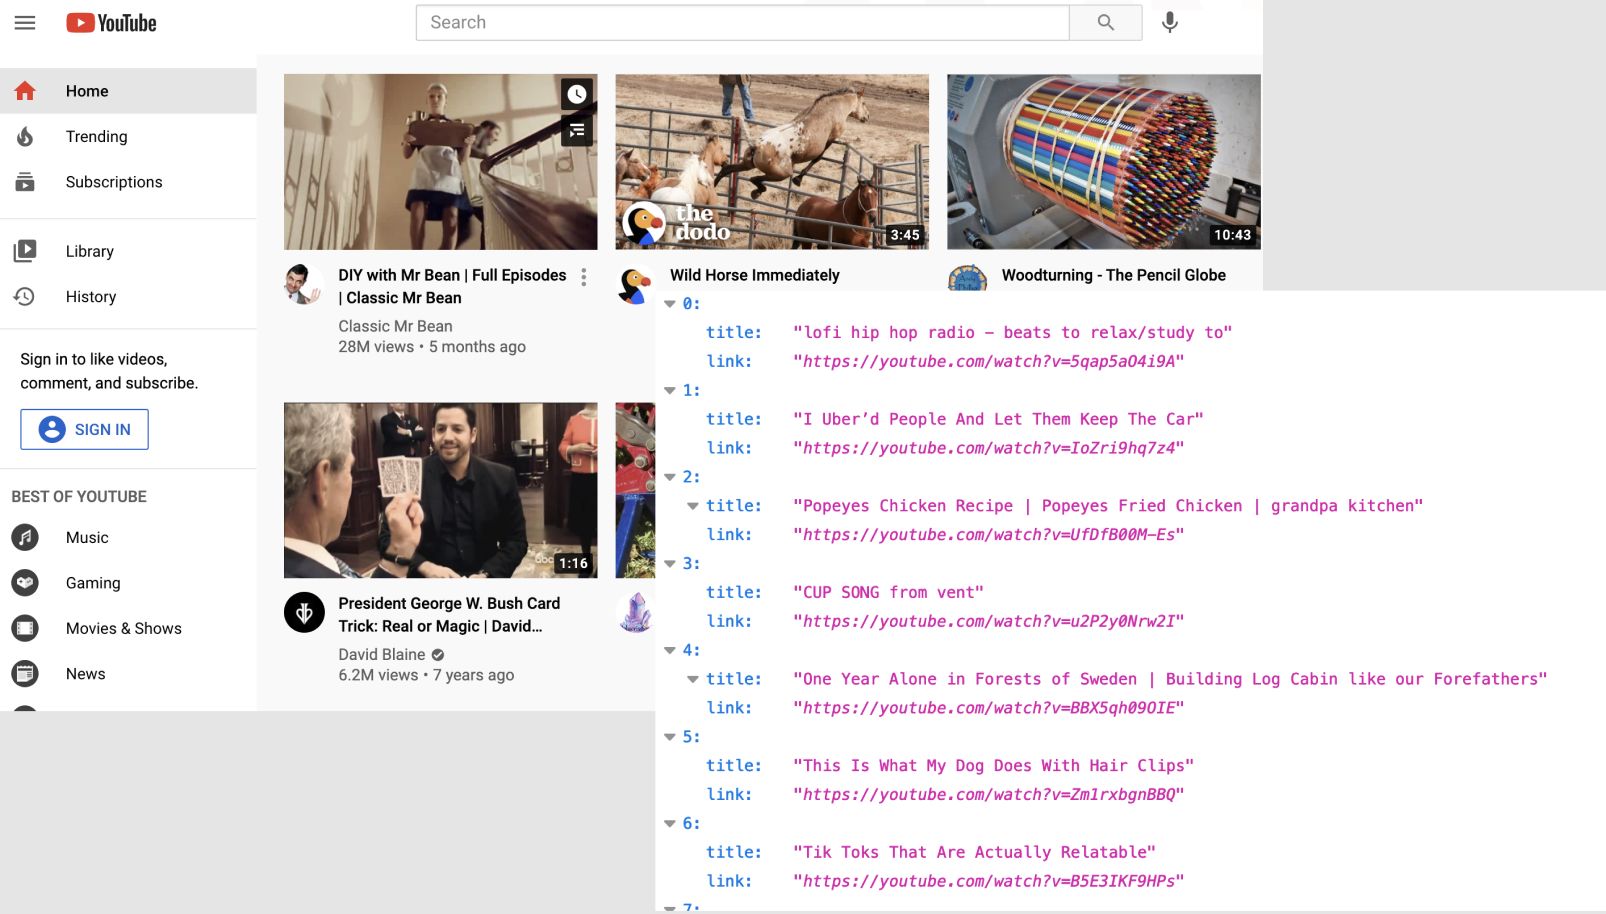 A guide to web scraping with Puppeteer, Node.js, and Autocode with tips and examples
49. Flix-Finder: Building a Movie Recommendation App With Django and BrightData [Part 1/3]
 Using Django & BrightData to build a Movie Recommendation Website! With ability to search through data of various rating agencies, Flix-Finder is a must have!
50. Scraping Ikea Website for Understanding Pricing Strategies in Different Countries
 Scraping Ikea website for every country to get insights about its pricing strategies (and have a quick view of the difficulties of web scraping).
51. How To Implement IP Rotation With Proxies
 Let's explore what IP rotation is all about and see how to implement it using proxies.
52. Why Agents Stall in Production: When Real-Time Retrieval Meets Reality
 Agents that work in demos fail at scale. Learn why 429/403 happen under concurrency and how to build reliable, accurate evidence acquisition.
53. The Best User Agent for Web Scraping
 Learn why you should set a user agent when scraping the web and discover the best user agent for web scraping
54. Write About Data Collection for AI and LLM Training, Win from $2500
 Enter the AI Writing Contest by December 1, 2024, to explore AI data collection with Bright Data and compete for a $2,500 prize pool.
55. How Data Analysis Helps Unveil the Truth of Coronavirus
 These days we are all scared of the new airborne contagious coronavirus (2019-nCoV). Even if it is a tiny cough or low fever, it might underlie a lethargic symptom. However, what is the real truth?
56. Playwright Vs Selenium: Comparing the Two
 A brief comparison between Selenium and Playwright from a web scraping perspective. Which one is the most convenient to use?
57. Web scraping using a headless browser in NodeJS
 Web scraping collects and extracts unstructured data from a website to a more readable structured format like CSV and more.
58. Designing a Scraping Platform: Generic Scrapers vs. Targeted Scrapers
 How to design a scraping platform?
59. Scraping the unscrapable in Python using Playwright
 Scraping the web is about extracting data in a clean and readable format that developers deploy to read and download an entire web page of its data ethically
60. How I Scraped YouTube Comments with Bright Data to Understand Customer Sentiment
 Learn how to scrape YouTube comments using Bright Data and Python.
61. Alternatives to Web Scraping with Python
 Is Python really the easiest and most efficient way to scrape a website? There are other options out there. Find out which one is best for you!
62. 5 Técnicas Anti-Scraping que Puedes Encontrar
 Con el advenimiento de los grandes datos, las personas comienzan a obtener datos de Internet para el análisis de datos con la ayuda de rastreadores web. Hay varias formas de hacer su propio rastreador: extensiones en los navegadores, codificación de python con Beautiful Soup o Scrapy, y también herramientas de extracción de datos como Octoparse.
63. Win Up to $2500 in the AI Writing Contest by Bright Data and HackerNoon
 Join the AI Writing Contest by Bright Data and HackerNoon! Share your insights on AI, LLMs, and web scraping for a chance to win from a $2500 prize pool.
64. From RAG to Instant Knowledge Acquisition: Giving Market-aware Agents Access to the Live Market
 RAG uses known docs. Market-aware agents
need live web evidence. Learn instant
knowledge acquisition and how it
enables accurate outputs.
65. Use Kali Linux Docker Containers to Support Covert Web Scraping
 Use Kali Linux Docker containers and host ephemeral environments to support covert web scraping via Tor Browser, and penetration testing of container networks.
66. Top 10 Best Web Scraper And Data Scraping Tools
 Data extraction has many forms and can be complicated. From Preventing your IP from getting banned to bypassing the captchas, to parsing the source correctly, headerless chrome for javascript rendering, data cleaning, and then generating the data in a usable format, there is a lot of effort that goes in. I have been scraping data from the web for over 8 years. We used web scraping for tracking the prices of other hotel booking vendors. So, when our competitor lowers his prices we get a notification to lower our prices to from our cron web scrapers.
67. Web Scraping with Python Using Regular Expressions
 In this tutorial, we will explore how to scrape web pages using Python and regular expressions.
68. Content Scraping: An Unforgivable Theft of Creativity
 We need to talk about the grim reality of content scraping—a cybercrime undermining creators.
69. My Journey Building a Scraper with Ruby

70. Cheerio? Playwright? A Young Devs Experience Web Scraping
 Web scrapers! JavaScript has Cheerio and Puppeteer. Python has Beautiful Soup, Playwright as well as others. Lets see how well these webs scrapers function.
71. How To Scrape Modern SPAs, PWAs, and AI-Driven Dynamic Sites
 Let's dig into advanced web scraping by looking at how to scrape SPAs, PWAs, and AI-powered sites
72. Web Crawling vs Scraping: What's the Difference Between Crawlers and Scrapers?
 Learn the fundamental distinctions between web crawling and web scraping, and determine which one is right for you.
73. A Step-by-Step Guide to Building a Football Data Scraper
 Scraping football data (soccer in the US) is a great way to build comprehensive datasets to help create stats dashboards. Check out our football data scraper!
74. The Role of the TLS Fingerprint in Web Scraping
 Let's learn what TLS fingerprinting is and why your TLS fingerprint can get you blocked when performing web scraping
75. How To Scrape Google With Python
 Ever since Google Web Search API deprecation in 2011, I’ve been searching for an alternative. I need a way to get links from Google search into my Python script. So I made my own, and here is a quick guide on scraping Google searches with requests and Beautiful Soup.
76. Bypassing JavaScript Challenges for Effective Web Scraping
 Let's learn everything you need to know about JavaScript challenges and how to bypass them in web scraping!
77. Automating the Automation: Can AI Fully Take Over the Data Scraping Process?
 Can modern AI systems fully automate web data collection and analysis? Let’s delve deeper into ML and web scraping to see if this is more than just a new hype.
78. AI CAPTCHA Fails Are the Internet’s New Comedy Show!
 Let's take a look at some AI CAPTCHA fails and explore a real tool for CAPTCHA automation.
79. How Bright Data Simplifies Web Scraping/Data Collection for AI Training
 How data scraping is made easy and efficient with Bright Data's powerful solution.
80. Web Scraping Use Cases for Technical Marketers
 From a technical marketer perspective, scraping and automation libraries are extremely important to learn. Here’s an introduction to two of the most widely used web scraping libraries in Node JS.
81. How to Scrape Amazon Reviews with and without Code
 Web-scrape Amazon reviews with and without Python code.
82. How to Avoid an IP Ban with Proxies
 Your IP has been banned? Don't worry! Read this guide and learn effective techniques to avoid an IP ban.
83. How To Scrape Wikipedia By Using Puppeteer and Nodejs
 Scraping Wikipedia for data using Puppeteer and Node
84. Extraer Datos del Website a Excel Automáticamente

85. Build a Bot that Automates Website Clicks Without Coding
 If you are looking for a way to automate browser website clicks, you came to the right place.
86. How to Use Data Science to Find the Best Seat in the Cinema (Part I)
 From the most popular seats to the most popular viewing times, we wanted to find out more about the movie trends in Singapore . So we created PopcornData — a website to get a glimpse of Singapore’s Movie trends — by scraping data, finding interesting insights, and visualizing them.
87. How to Build a No-Limits Stock Market Scraper with Python
 Frustrated with stock market API limits? I built a Python web scraper to fetch real-time and historical financial data for free.
88. Deadline Extended: 2 Weeks Left to Compete for $2,500 in the AI Writing Contest
 The AI Writing Contest deadline has been extended to December 16, 2024! Explore data collection for AI and LLM training, and compete for $2,500. Enter now!
89. Proxy Servers for Your Data Science Project: A Comprehensive Guide
 A data-driven intro to proxies in the context of web scraping.
90. Tutorial: How to Turn YouTube Videos Into Twitter Threads Using AI
 Tutorial to convert YouTube videos into engaging Twitter threads using AI in this step-by-step tutorial.
91. How To Monitor a Forum for Keywords Using Python and AWS Lambda
 While building ScrapingBee I'm always checking different forums everyday to help people about web scraping related questions and engage with the community.
92. AutoScraper Introduction: Fast and Light Automatic Web Scraper for Python
 In the last few years, web scraping has been one of my day to day and frequently needed tasks. I was wondering if I can make it smart and automatic to save lots of time. So I made AutoScraper!
93. The Evolution of Big Data And Web Scraping
 As the CEO of a proxy service and data scraping solutions provider, I understand completely why global data breaches that appear on news headlines at times have given web scraping a terrible reputation and why so many people feel cynical about Big Data these days.
94. How to Make the Most of Playwright After the Latest Updates
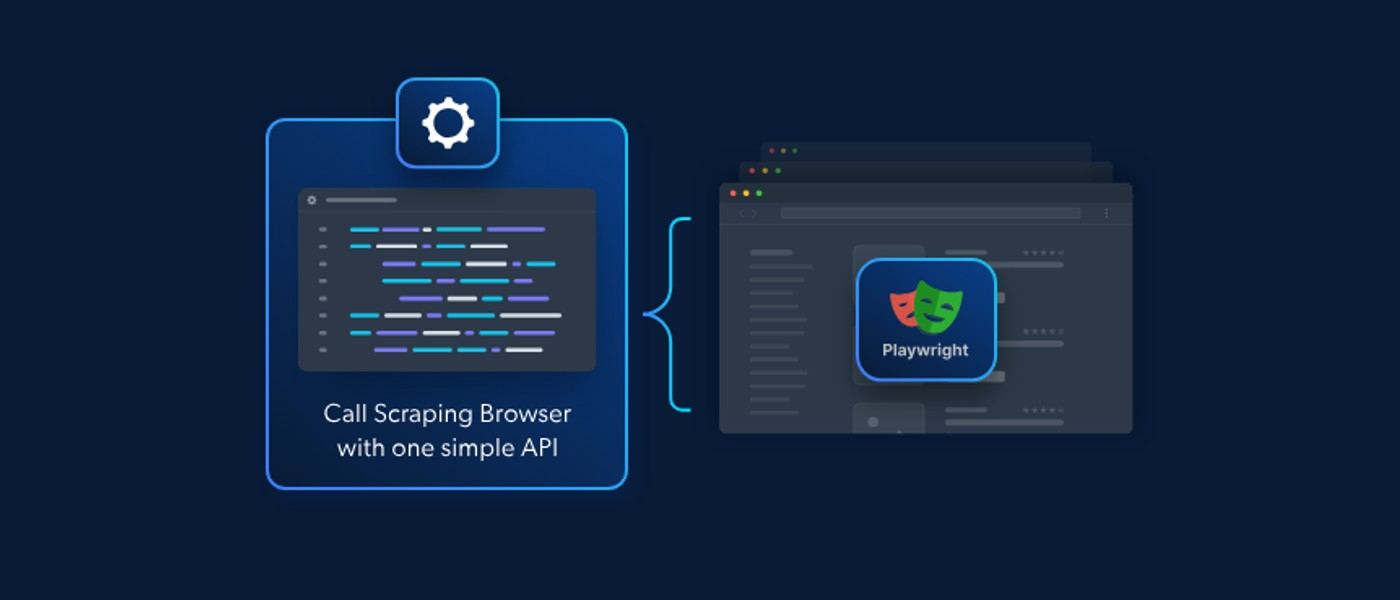 Playwright is the rock star of browser automation libraries, and just like Santa Claus delivers presents on Christmas Eve... Learn more about the latest update.
95. Scraping A Website with Python and Selenium: A How-To Guide
 web scraping is practiced by businesses that create their marketing and development strategies based on the vast amount of web data
96. The 5 Best X (Twitter) Scraping Tools: Scrape Tweets, Export Followers & More
 This article lists the 5 best X (Twitter) scraping tools available today. We’ll explore what makes each tool unique, focusing on their capabilities for tasks li
97. Data Gathering Methods: How to Crawl, Scrape, and Parse Data Online
 The internet is a treasure trove of valuable information. Read this article to find out how web crawling, scraping, and parsing can help you.
98. OpenAI’s Operator vs CAPTCHAs: Who’s Winning?
 Let's see how OpenAI's Operator is handling CAPTCHAs and explore whether this is the best solution!
99. Defeating TLS Fingerprinting: Bypassing Firewall Protection for HTTPS Requests
 Bypass firewall protections and successfully scrape HTTPS data by understanding and defeating TLS fingerprinting using JavaScript and curl commands.
100. Web scraping: why small business should take this opportunity?
 The business world is a very cold and hard place where only the best find their way to succeed. The market — each market — has its own limits and even if it’s pretty easy to get into the market, the most difficult part comes when you have to find a way to stay in that market and grow your business when the competition is always growing.
101. Differences in Top Search Results Between Google and Alternative Search Engines
 Explore the results and insights from a study comparing search engine domains across Google, Bing, DuckDuckGo, and Metager.
102. Scraping Google Shopping Using Puppeteer and Browserless
 An easy tutorial showcasing the power of puppeteer and browserless. Scrape Google Shopping to gather prices of specific items automatically!
103. How to Create a COVID Vaccine Slot Availability Notifier Using Python
 Coronavirus cases are increasing day by day. It’s very important to get vaccinated. so I tried to create an automated notifier to tell me when a lost opened up.
104. Elevate Your Scraping Project With Puppeteer Extra
 Let's explore everything you need to know about Puppeteer Extra, the enhanced version of Puppeteer that adds support for plugins
105. You’ll Need to Use a Proxy Server, Sooner or Later
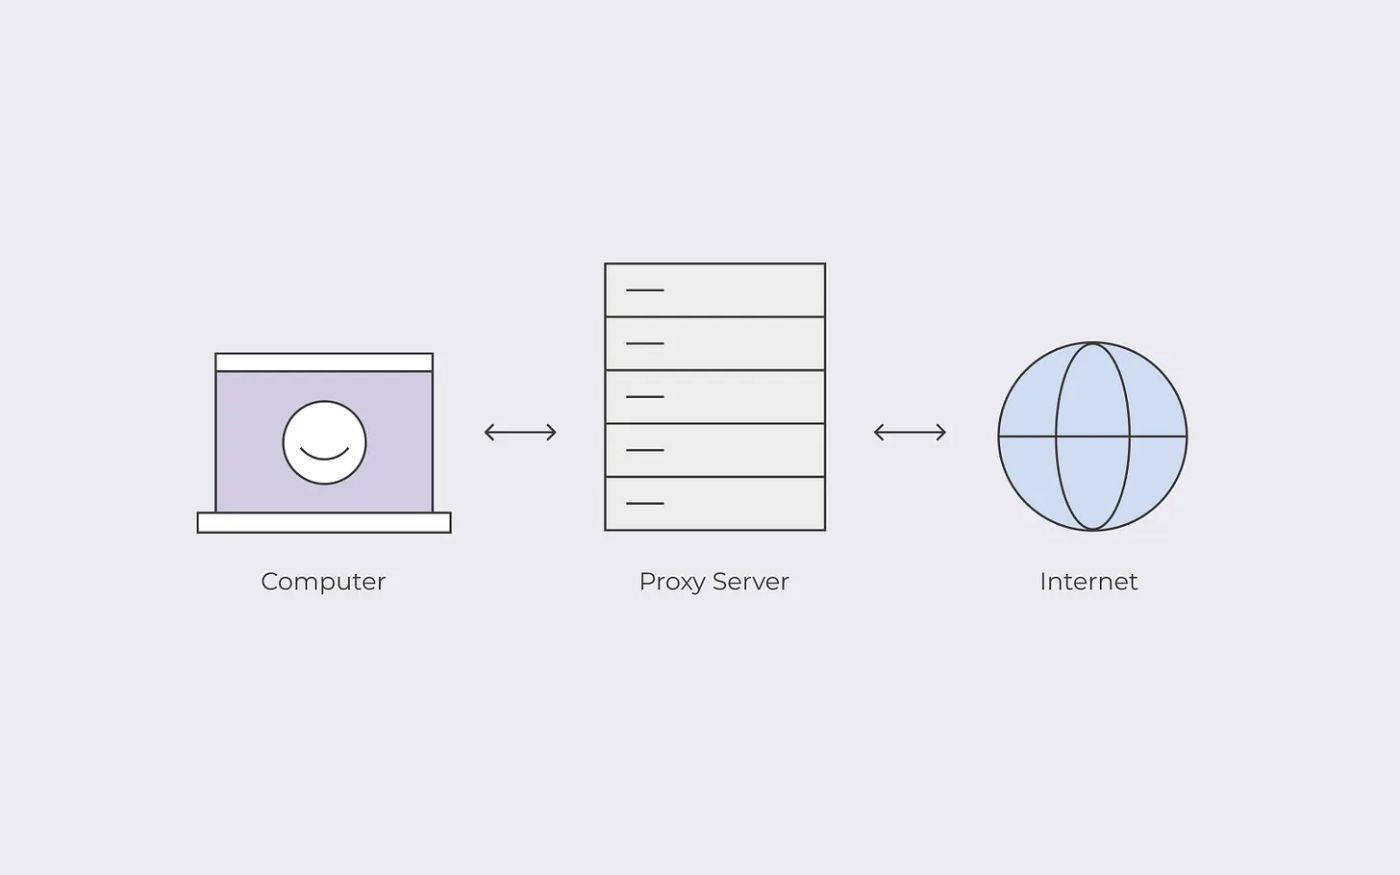 Why in large web scraping projects there's the need of proxy servers? Here a brief explanation of what they are and how they work and their differences.
106. Data Scraping in Node.js 101
 How to gather data without those pesky databases.
107. Visualizing Healthcare Budget using Web Scraping in Python

108. Top 5 Anti-Scraping Measures You Need To Know
 Let's dig into the most popular anti-scraping measures on the market to become a real scraping ninja!
109. Meet Oxylabs: HackerNoon Company of the Week
 Meet Oxylabs, a business intelligence software company and HackerNoon's Company of the Week.
110. Why Are the New AI Agents Choosing Markdown Over HTML?
 Let's find out why AI agents convert HTML to Markdown to cut token usage by up to 99%!
111. Utilizing Web Scraping and Alternative Data in Financial Markets
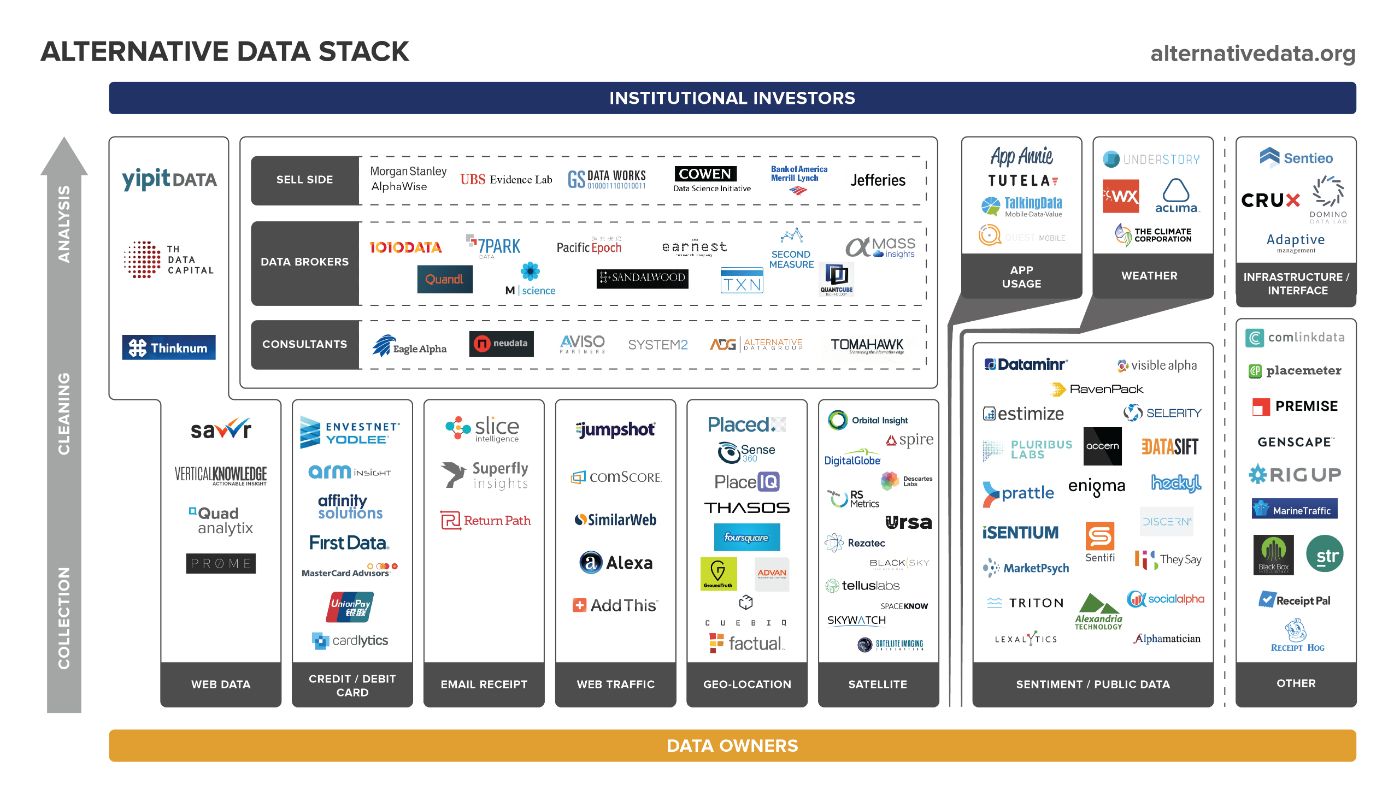 What are alternative data and how to use web scraping to build datasets for financial markets?
112. An Introduction to cURL: The Most Popular HTTP Client
 Let's learn everything you need to know about the most popular CLI HTTP client in this guide to cURL.
113. Let's Build a Free Web Scraping Tool That Combines Proxies and AI for Data Analysis
 Learn how to combine web scraping, proxies, and AI-powered language models to automate data extraction and gain actionable insights effortlessly.
114. What is Web Data Collection?
 Everything you need to know to automate, optimize and streamline the data collection process in your organization!
115. Scrape And Compare eCommerce Products Using Proxy Scraper
 In this post, we are going to learn web scraping with python. Using python we are going to Scrape websites like Walmart, eBay, and Amazon for the pricing of Microsoft Xbox One X 1TB Black Console. Using that scraper you would be able to scrape pricing for any product from these websites. As you know I like to make things pretty simple, for that, I will also be using a web scraper which will increase your scraping efficiency.
116. Navigating Advanced Web Scraping: Insights and Expectations
 Let's get an introduction to the complex world of advanced web scraping techniques and approaches.
117. The A-Z of Web Scraping in 2020 [A How-To Guide]

118. Scraping with Selenium 101: The Big Hole on Data Scientists Toolset [Part 1]
 Usually forgotten in all Data Science masters and courses, Web Scraping is, in my honest opinion a basic tool in the Data Scientist toolset, as is the tool for getting and therefore using external data from your organization when public databases are not available.
119. Staying Ethical and Legal in the Age of AI Web Scraping
 Let's explore the world of ethical and legal web scraping, uncovering the new factors to consider in the age of AI.
120. Web Scraping Optimization: Tips for Faster, Smarter Scrapers
 Let's dive into advanced web scraping tips for optimization. Take your scraper to the next level!
121. The Power of AI-Driven Proxy Management
 Let's learn everything you need to know about AI proxies to take your scraping game to the next level!
122. Web Scraping with python
 In this post, we are going to scrape Yahoo Finance using python. This is a great source for stock-market data. We will code a scraper for that. Using that scraper you would be able to scrape stock data of any company from yahoo finance. As you know I like to make things pretty simple, for that, I will also be using a web scraper which will increase your scraping efficiency.
123. How to Master Web Scraping in Python: From Zero to Hero
 Pro Tips & Techniques to Scrape Any Website Reliably. Go beyond CSS selectors to get hidden content. Metadata is full of valuable information.
124. Web Scraping 101: Abordar La Paginación para Web Scraping
 La paginación es una técnica ampliamente utilizada en el diseño web que divide el contenido en varias páginas, presentando grandes conjuntos de datos de una manera mucho más fácil de digerir para los internautas.
125. An Intro to Web Scraping: What it is and How to Start
 A quick introduction to web scraping, what it is, how it works, some pros and cons, and a few tools you can use to approach it
126. Streamlining AI Data Collection with Bright Data’s Scraping Browser
 Streamlining AI data serves as a means to support companies needing extensive training data and capitalizing on building efficient models.
127. Avoid Getting Caught in a Honeypot Trap When Scraping the Web
 See what a honeypot trap is and learn everything you need to know about this effective anti-bot mechanism.
128. How to Scrape Large Datasets at Scale
 Using Bright Data’s Web Scraper IDE to scrape datasets at scale using its ready-made functions and coding templates.
129. Asked for a Parka, Got an “Error 429: Too Many Requests”
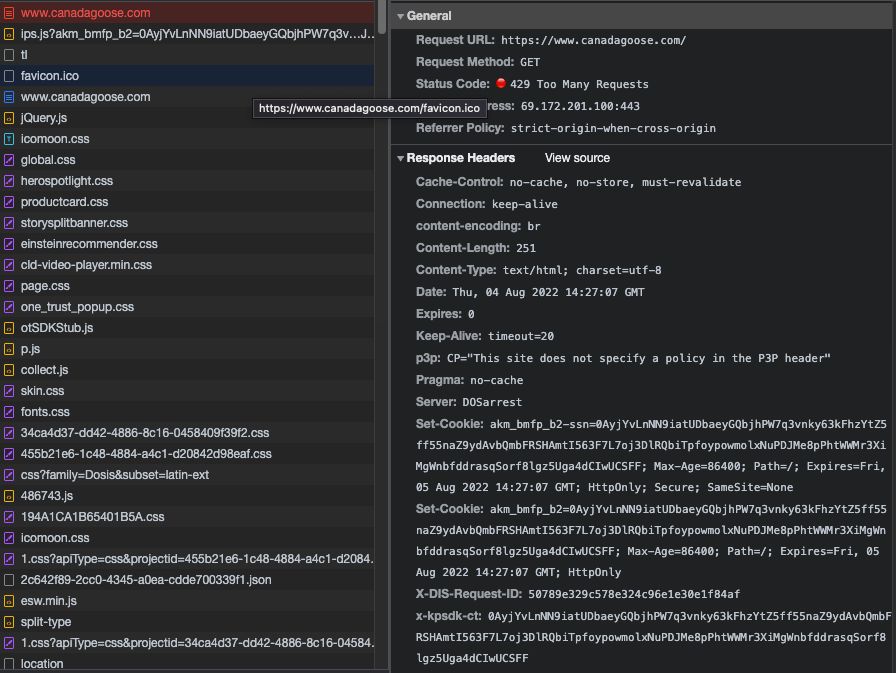 Anti-bot techniques are getting life harder for web scrapers. In this post we'll see how Kasada protects a website and how a misconfiguration of it can be used
130. Behind the Scenes of Using Web Scraping and AI in Investigative Journalism
 Learn how journalists utilize web scraping software for investigative research.
131. Mastering Dynamic Web Scraping
 In a recent webinar, web automation experts share pro tips to navigate this landscape using Selenium, Playwright and Puppeteer.
132. We Kinda Bypassed Firebase's Paywall: Here's How
 Some time ago, a few friends and I decided to build an app. We duck-taped our code together, launched our first version, then attracted a few users with a small marketing budget.
133. 20 Herramientas de Inteligencia Empresarial (BI) más Populares en 2020
 Business Intelligence (BI) es un negocio basado en datos, un proceso de toma de decisiones basado en datos recopilados. A menudo es utilizado por gerentes y ejecutivos para generar ideas procesables. Como resultado, BI siempre se conoce indistintamente como "Business Analytics" o "Data Analytics".
134. How to Scrape Bestbuy Products with Scrapezone SDK
 Welcome to the new way of scraping the web. In the following guide, we will scrape BestBuy product pages, without writing any parsers, using one simple library: Scrapezone SDK.
135. Building a Layered Defense Against Web Scraping
 Discover how a three-layer data-protection model blends AI, risk-based gating, and legal context to stop web scraping while preserving user trust.
136. Analyzing 110 Million Comments from Hacker News
 In this article, we’ll observe another test with1.1M Hacker News curated comments with numeric fields
137. Understanding the Fundamentals of Device Fingerprinting
 A device fingerprint - or device fingerprinting - is a method to identify a device using a combination of attributes provided by the device itself, via its brow
138. How to Scrape Any Website Using Bright Data MCP Server and AI Agents
 Built a real-time sneaker scraper using Bright Data’s MCP Server, LangChain, Claude, and FastAPI. This tool bypasses scraping blocks and extracts live Nike prod
139. [Tutorial] How To Scrape Websites by using Puppeteer - A Headless Browser From Google
 Web development has moved at a tremendous pace in the last decade with a lot of frameworks coming in for both backend and frontend development. Websites have become smarter and so have the underlying frameworks used in developing them. All these advancements in web development have led to the development of the browsers themselves too.
140. Scraping Tesla Stock Prices with Node.js and Puppeteer
 Learn how you can easily scrape the latest stock prices using Node.js and puppeteer!
141. A Quick Primer on Data Scraping
 Suppose you want to get large amounts of information from a website as quickly as possible. How can this be done?
142. The Ultimate Tutorial On How To Do Web Scraping
 Mastering Web-Scraping like a boss. Data Extraction Tips & Insights, Use Cases, Challenges... Everything you need to know🔥
143. Playwright: My First Steps With the Browser Automation Tool
 Playwright is a browser automation tool with a couple of language APIs, including Python.
144. A Comparison of Source Distribution and Result Overlap in Web Search Engines
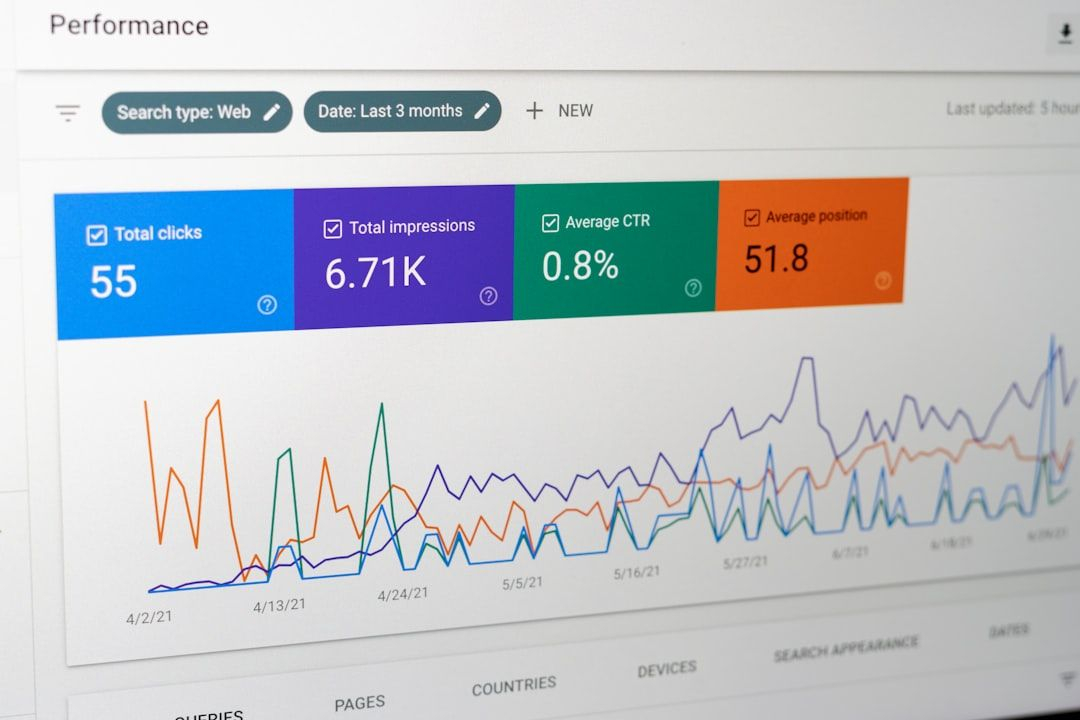 Discover the differences in search results between Google and alternative search engines like Bing, DuckDuckGo, and Metager.
145. Scraping Google Search Console Backlinks
 Learn how to emulate a normal user request and scrape Google Search Console data using Python and Beautiful Soup.
146. Web Scraping Using Node.js
 While there are a few different libraries for scraping the web with Node.js, in this tutorial, i'll be using the puppeteer library.
147. Oxylabs Has Changed How Web Scraping Is Done With a New AI-Powered Solution
 Oxylabs' AI-driven tool, OxyCopilot, simplifies web data collection, saving time and money by automating complex tasks using just a URL and natural prompts.
148. A Guide on How to Legally Web Scrape EU Data
 Scraping has long existed in a legally gray area, so journalists and other researchers tend to approach it cautiously.
149. Proxies: How They Work and Why They're Essential
 Explore how proxies enhance online privacy and security, including types like data center and residential proxies. Learn proxy usage in Python for web scraping.
150. Automating reCAPTCHA Solving: Why and How
 Let's learn everything you need to know about how to automate reCAPTCHA, the most popular CAPTCHA provider by Google.
151. How to Scrape Domain.com.au Real Estate Data with Apify Actor
 Learn how to scrape real estate listings from Domain.com.au using an Apify actor. Extract property details, pricing, agent info, and more.
152. The Complete Guide to Building Your Own Web Scraper With NodeJS
 When you need tons of data quickly, a web scraper is the best option. Luckily, making your own scraper isn't as hard as it seems. Here's how to do it in NodeJS!
153. Web Scraping with Javascript and Node.js
 Learn how to build a web scraper with Javascript and Node.js. Add anti-blocking techniques, a headless browser, and parallelize requests with a queue.
154. What's the Deal With Data Engineers Anyway?
 Learn the basics of data engineering with a practical ETL pipeline project. Explore how weather, flight, city data are extracted, transformed, loaded into a DB.
155. Data Scraping Google Search Results Using Python and Scrapy
 Scraping Google SERPs (search engine result pages) is as straightforward or as complicated as the tools we use.
156. Streamlining Workflow with Puppeteer
 My journey of streamlining my workflow with Puppeteer.
157. The AI Writing Contest by Bright Data & HackerNoon: Results Announcement 🎉
 The AI Writing Contest winners are here! See who won $2,500 in prizes for top AI, web scraping, and Bright Data stories.
158. In the future, your data is more valuable than gold
 The value of your data is defined by the persona built about you, including who you are and all your preferences.
159. When Should I Use an HTTP/HTTPS Sniffer?
 In this article, I will tell you what role the HTTP/HTTPS sniffer plays in data parsing and why it is very important.
160. How to Make Money Scraping the News in 2024
 Presenting a a powerful tool that allows you to quickly and efficiently gather large amounts of news articles from various sources.
161. Why You Should Stop Your Reading Challenge
 Image: Goodreads.com
162. 3 Mejores Formas de Crawl Datos desde Website
 La necesidad de crawling datos web ha aumentado en los últimos años. Los datos crawled se pueden usar para evaluación o predicción en diferentes campos. Aquí, me gustaría hablar sobre 3 métodos que podemos adoptar para scrape datos desde un sitio web.
163. Send Me A Text Message when BTC Hits $30K: A NodeJS Project
 For a while, nobody in my circle of friends was talking about crypto.
164. Mastering Scraped Data Management (AI Tips Inside)
 Let's explore a few techniques to handle scraped data, including automatic data processing via AI.
165. Decoding Web Scraping with Python — A Guide
 Web scraping has become an important technique for extracting valuable information from websites.
166. Top Scraping Tools for Amazon
 Scraping Amazon is challenging. Hence, having the right tools is crucial. I compared three tools based on their price, performance, and features.
167. Need Web Data? Here Are the 3 Methods Everyone’s Using
 Discover the three best, most modern methods to access and harness web data for your projects.
168. Alternatives to LinkedIn Sales Insights Tool
 LinkedIn has just announced it will sunset Sales Insights. What’s next? The solution lies in web scraping!
169. How Web Scraping Helps Businesses Outperform Their Competition

170. Scraping Amazon Reviews using Scrapy in Python [Tutorial]
 Are you looking for a method of scraping Amazon reviews and do not know where to begin with? In that case, you may find this blog very useful in scraping Amazon reviews. In this blog, we will discuss scraping amazon reviews using Scrapy in python. Web scraping is a simple means of collecting data from different websites, and Scrapy is a web crawling framework in python.
171. Comparative Analysis of Search Engine Results Using Google Trends Data
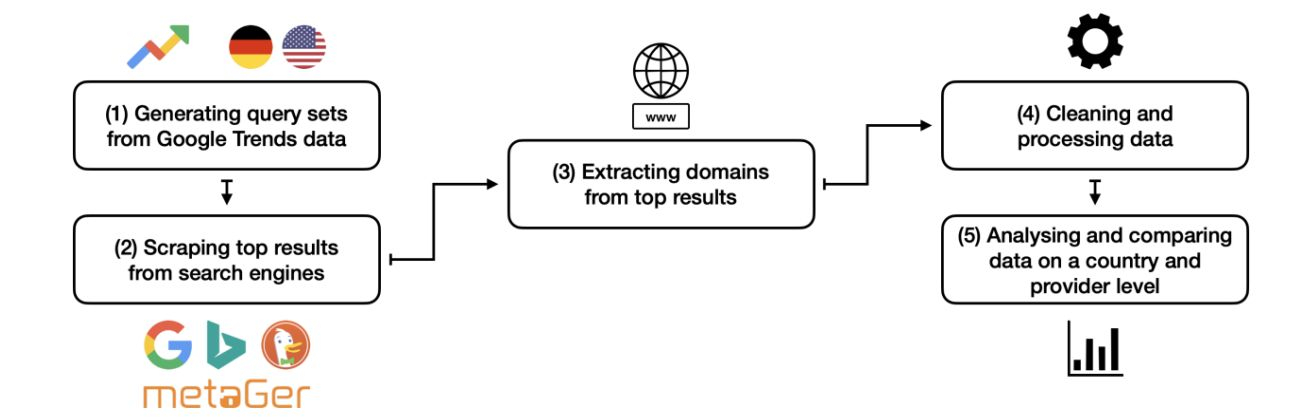 Learn about the methodology used in a comprehensive study comparing search engine results from Google, Bing, DuckDuckGo, and Metager.
172. How to Web Scrap with Python lxml [Beginner's Guide]
 Web Scraping with Python is a popular subject around data science enthusiasts. Here is a piece of content aimed at beginners who want to learn Web Scraping with Python lxml library.
173. Differences and Applications of Web Scraping and Data Mining
 Learn the differences between web scraping and data mining and how to apply them.
174. Graphing How Many Times People Liked my Posts on Instagram
 Visualising knowledge in a (somewhat) readable way, so you can flex on your friends and show your data collection skills.
175. It’s in the Data: How COVID-19 is Affecting the Digital Landscape

176. Web Scraping for Good: Utilising the Power of Data Ethically
 How can web scraping deliver a significant positive impact and serve non-profit, socially important causes?
177. 53 Stories To Learn About Data Scraping
 Learn everything you need to know about Data Scraping via these 53 free HackerNoon stories.
178. How I Made a Ten Line Ruby Script to Get My 1st Jab
 Use a Ruby script to get the jab in India
179. AI's New Data Economy Has a Landlord Problem
 AI licensing deals generate millions, but creators see little of it. This article examines the growing gap in the data economy.
180. Las 15 preguntas más frecuentes sobre Web Scraping
 Previously published at https://www.octoparse.es/blog/15-preguntas-frecuentes-sobre-web-scraping
181. Examining Source Diversity in Web Search: A Comparative Study of Top Search Engines
 Explore a comprehensive analysis of search result overlaps and source diversity across major search engines like Google, Bing, and meta search engines.
182. Improve Early Failure Detection (EFD) in Web Scraping With Benchmark Data
 We need to increase the Failure Detection Rate (FDR) and reduce the False Alarm Rate (FAR). With a cherry on top: keeping costs low.
183. Exploring Benefits of Using Alternative Search Engines
 Discover how using alternative search engines can enhance search experience and provide more diverse results.
184. Elon Musk and X Corp. Are Trying To Make Web Scraping Legally Perilous Again - Here's How
 It seeks tens of millions of dollars in damages from a nonprofit that produced research into the prevalence of hate speech on X’s platform.
185. Tips On Web Scraping to Find Amazon’s Bestselling Products

186. How Different Search Engines Display and Prioritize Information
 Gain valuable insights into how different search engines display and prioritize information.
187. Final Call: Less Than a Month Left To Win From $2,500 in the AI Writing Contest
 Explore data collection for AI and LLM training in the AI writing contest on HackerNoon. Submit your entry by December 1, 2024, for a chance to win from $2,500.
188. The Ouroboros Effect of Data Aggregation and Scraping
 Learn how web scraping and data aggregation might feed of each other, unintentionally creating an effect of decision-making convergence.
189. Domain Classification: Analyzing Source Types in Search Engine Results
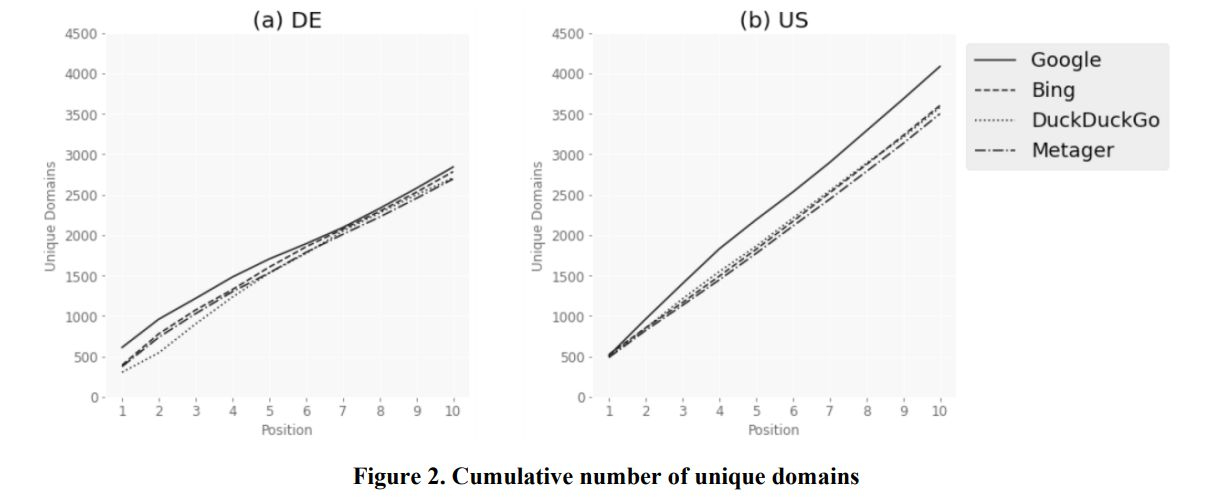 Explore the results and insights from a study comparing search engine domains across Google, Bing, DuckDuckGo, and Metager.
190. Why You Should Identify a Standard Structure When Capturing Web Data from E-Commerce Webs
 Capturing web data from e-commerce websites is very common but it's valuable to identify a standard structure first.
191. Solving Challenges of Data Acquisition in Retail: Alpha Capture in Digital Commerce
 In this part of the ‘Alpha Capture in Digital Commerce series’,we will explore the challenges of data acquisition in retail and discuss data science application
192. Use Jupyter to Restart the Script from the Point Where the Scrapper Terminated

193. Web Scraping API para Extracción de Datos: Una Guía para Principiantes
 ¿Alguna vez te sucede cuando la gente te pide que escribas una API separada para integrar datos de redes sociales y guardar los datos sin procesar en tu base de datos de análisis en el sitio? Definitivamente quieres saber qué es la API, cómo se usa en web scraping y qué puede lograr con ella. Echemos un vistazo.
194. Web Scraping: Is C# or JavaScript the Superior Choice?
 C# and JavaScript each have their own advantages and disadvantages in web crawling. The choice of language depends on specific needs and development environment
195. How to Scrape Data Off Wikipedia: Three Ways (No Code and Code)
 Get your hands on excellent manually annotated datasets with Google Sheets or Python
196. How Can Web Scraping Enhance LLM Performance? Share Your Thoughts To Win a Share of $2500
 Join the AI writing contest sponsored by Bright Data and HackerNoon by December 1, 2024, for a chance to win a share of $2500!
197. I Looked at the Source Code of 250,000 Shopify Stores
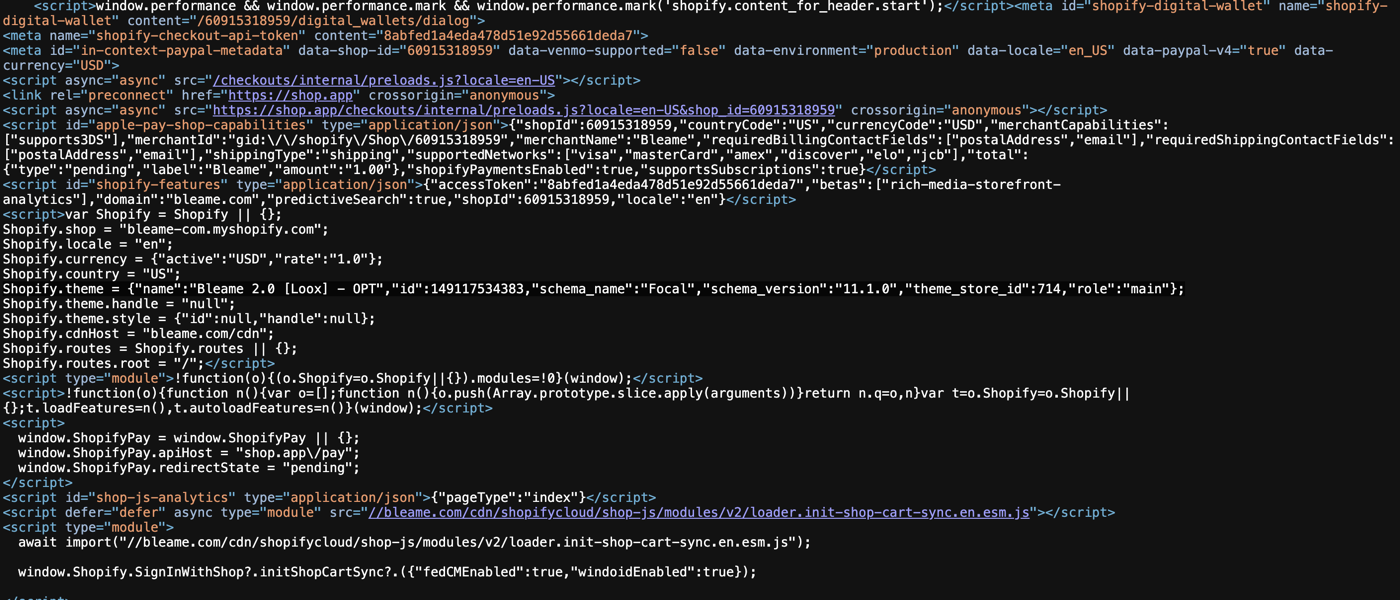 I scraped 250K Shopify stores. 52% run zero or one app. 59% have no email. 78% have no reviews. Here's the full data.
198. How to Create an Authentic Data Science Project for your Portfolio
 Follow me along on how I explored Germany’s largest travel forum Vielfliegertref. As an inspiring data scientist, building interesting portfolio projects is key to showcase your skills. When I learned coding and data science as a business student through online courses, I disliked that datasets were made up of fake data or were solved before like Boston House Prices or the Titanic dataset on Kaggle.
199. I Had to Reverse-Engineer React, Shadow DOM, and CSP to Automate Safari Without Chrome
 Learn how to automate Safari without Chrome DevTools Protocol by solving React state, Shadow DOM, and CSP challenges.
200. How By Scraping Amazon Data You Can Improve Prices of Your Products
 Amazon is one of the largest e-commerce platforms across the globe. It has one of the largest customer bases and one of the most versatile and adaptive product portfolios. It definitely gets the advantage of a large amount of data and better operational processes in place due to its standing as one of the largest retailers. Having said that, even you can use Amazon’s data as an advantage to yourself to design a better product and price portfolio.
201. How to Apply Web Scraping in Marketing
 Both large and small businesses rely more and more on web crawling to boost their marketing efforts.
202. Mapping India’s Hidden 10-Minute Grocery Warehouses
 How I reverse-engineered the APIs of India's quick-commerce giants (Blinkit, Zepto, Swiggy) to map 4,000+ hidden dark stores.
203. How to Avoid Unnecessary Data and Network Requests in Playwright
 Block specific resources from downloading with Playwright. Save time and money by downloading only the essential resources while web scraping or testing.
204. Web Scraping Social Media for Business Growth
 You may be surprised to hear that there's a wealth of useful data out there, just beyond the confines of your usual sources.
205. What Does Your AI Agent Need to Conquer the Web?
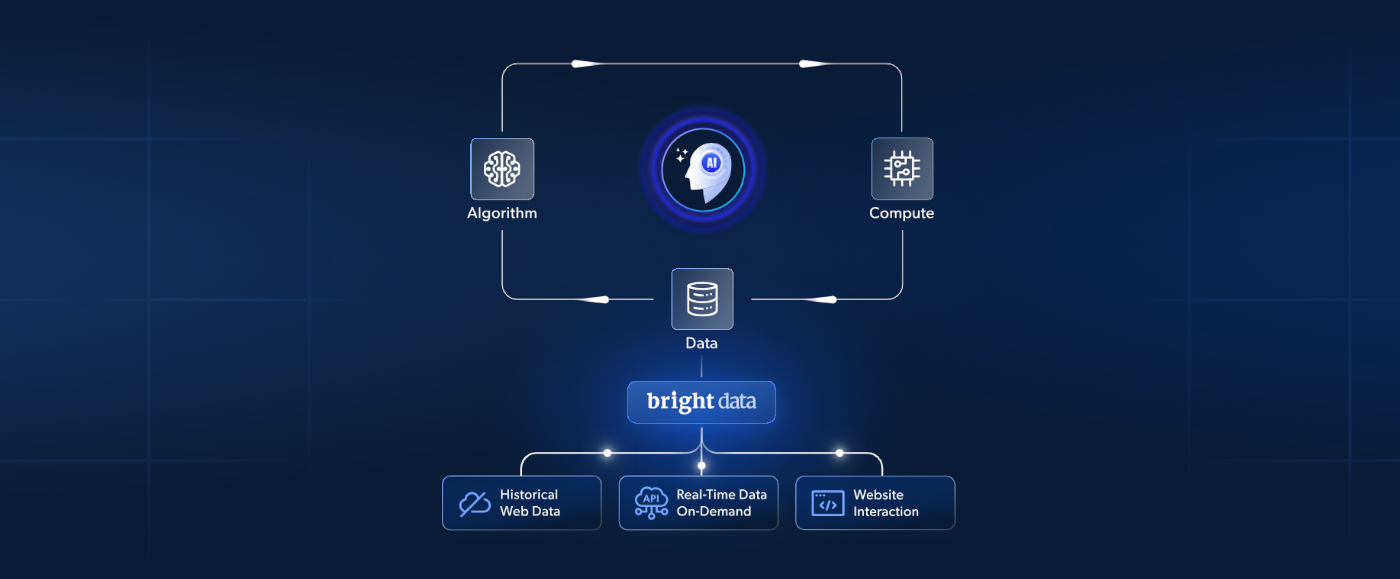 Let’s explore what your AI agent truly needs to unlock its full potential and conquer the Web!
206. Automation for Girl Scout Events
 The shutdowns brought an opportunity for my daughter to participate in virtual scouting events all over the United States. When the event registration form changed, I took the chance to try out some new web scraping skills while inspiring my daughter about the power of code for everyday tasks.
207. Big Data: 70 Increíbles Fuentes de Datos Gratuitas que Debes Conocer para 2020
 Por favor clic el artículo original:http://www.octoparse.es/blog/70-fuentes-de-datos-gratuitas-en-2020
208. Broken Link Building With Proxies: A How-To Guide
 Broken Link Building – 29.9% New Users, A Higher DR, and a Revenue Boost of 42.3%
209. Harnessing Public Web Data for AI
 Unlock AI's potential with Bright Data! Discover methods, tackle challenges, and use pre-configured datasets for efficient, compliant public web data collection
210. How to Use Web Scraping to Empower Marketing Decisions
 Learn how to leverage web scraping in marketing. In this article, we unpack use cases and tips for getting started.
211. You Don’t Need an API for Everything (Sometimes Scraping Is Enough)
 You don't always need an API. Sometimes scraping public pages is the simplest, fastest way to turn repetitive browsing into usable data.
212. The HackerNoon Newsletter: Surviving the Google SERP Data Crisis (2/2/2025)
 2/2/2025: Top 5 stories on the HackerNoon homepage!
213. How One EU Announcement Killed Our AI App Launch
 The story of two founders who built a site that tracks liquid rules, airport info, and travel tips, only to have it crushed by a single EU announcement.
214. Meet Data: The Driving Power of Fintech
 Off late, “Fintech” has been and remains to be a buzzword. It is transcending beyond traditional banking and financial services, encompassing online wallets, crypto, crowdfunding, asset management, and pretty much every other activity that includes a financial transaction. Thereby competing directly and fiercely with traditional financing giants and their methods.
215. Parsing as Response Validation: A New Necessity for Scraping?
 Find out how parsing has moved upstream to support accurate data collection
216. Gaming the System in the Search for AI Data
 An AI story, written by a naive human, about how to solve the outstanding AI data question. Perhaps we could recreate a world, a world with data.
217. Web Data Can Have Quality Issues — Here's How Ground Truth Testing Can Help
 Data (bad) quality is an issue with all kinds of data. Quality Assurance (QA) represents a significant portion of the effort of data projects.
218. Balancing Privacy and Personalization With ML-Powered Advertising Solutions
 Contextual advertising is on the rise, offering a more effective and less costly solution for personalization. Learn more about how ML can drive it further.
219. The HackerNoon Newsletter: Netflix and Amazon: A Tale of Two Ad Tiers (11/14/2024)
 11/14/2024: Top 5 stories on the HackerNoon homepage!
220. The HackerNoon Newsletter: Surviving the Google SERP Data Crisis (1/23/2025)
 1/23/2025: Top 5 stories on the HackerNoon homepage!
221. The Noonification: Patience is Beautiful (6/2/2023)
 6/2/2023: Top 5 stories on the Hackernoon homepage!
222. What's the Link Between Web Automation and Web Proxies?
 Web automation and web scraping are quite popular among people out there. That’s mainly because people tend to use web scraping and other similar automation technologies to grab information they want from the internet. The internet can be considered as one of the biggest sources of information. If we can use that wisely, we will be able to scrape lots of important facts. However, it is important for us to use appropriate methodologies to get the most out of web scraping. That’s where proxies come into play.
223. The HackerNoon Newsletter: Lumoz RaaS Introduces Layer 2 Solution on Move Ecosystem (11/24/2024)
 11/24/2024: Top 5 stories on the HackerNoon homepage!
224. The HackerNoon Newsletter: How to Tell if AI Really is a Revolution (5/6/2025)
 5/6/2025: Top 5 stories on the HackerNoon homepage!
Thank you for checking out the 224 most read blog posts about Web Scraping on HackerNoon.
Visit the /Learn Repo to find the most read blog posts about any technology.